18 octobre 2026 · 50 familles · inventaire de 3,16 millions de dépôts · audit indépendant Claude Code
Scénario des 50 familles : 834 M$ (281 M$–3,46 Md$). Pas un total Hub complet, ni des factures observées, ni un intervalle de confiance. Le premier milliard reste une hypothèse exploratoire. Les tarifs de conversion du calcul sont estimés même quand les volumes sont publiés.
Rapport et méthodologie · CSV familles · CSV composantes · CSV organisations · Télécharger les données et graphiques
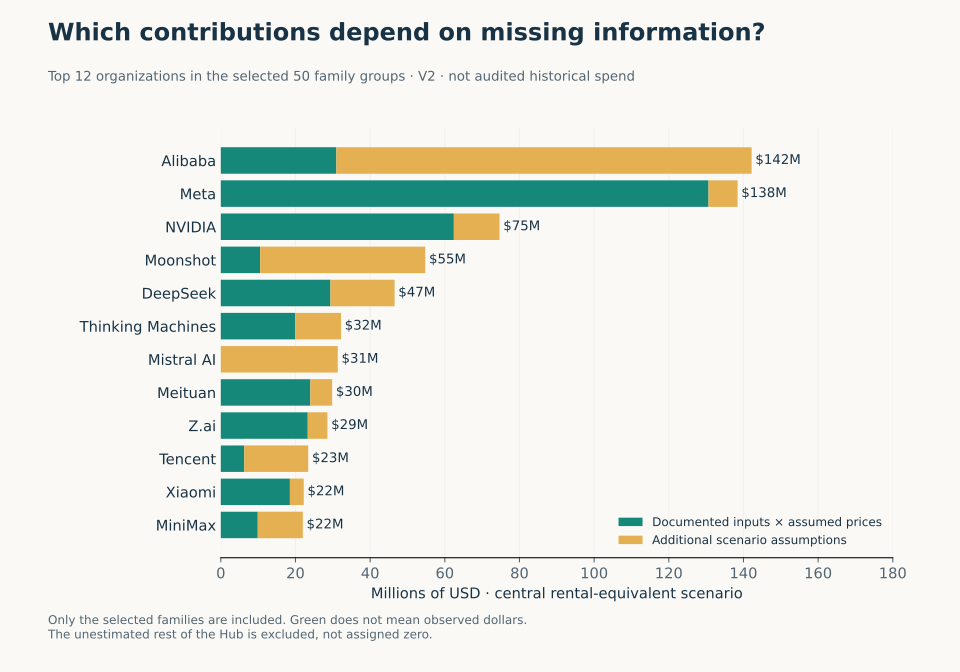
Les 15 familles dominantes ont été auditées indépendamment. Corrections retenues : tokens effectivement entraînés de Nemotron, budgets explicites de Qwen3-Coder/Next, heures Llama3.2 et tokens Inkling. Les changements de priors sans nouvelle donnée et les filiations déduites seulement des architectures ne sont pas considérés comme prouvés.
Source : cfahlgren1/hub-stats, snapshot du 17 octobre 2026. 3 161 594 identifiants distincts. Les fichiers atypiques et les liens externes restent à vérifier.
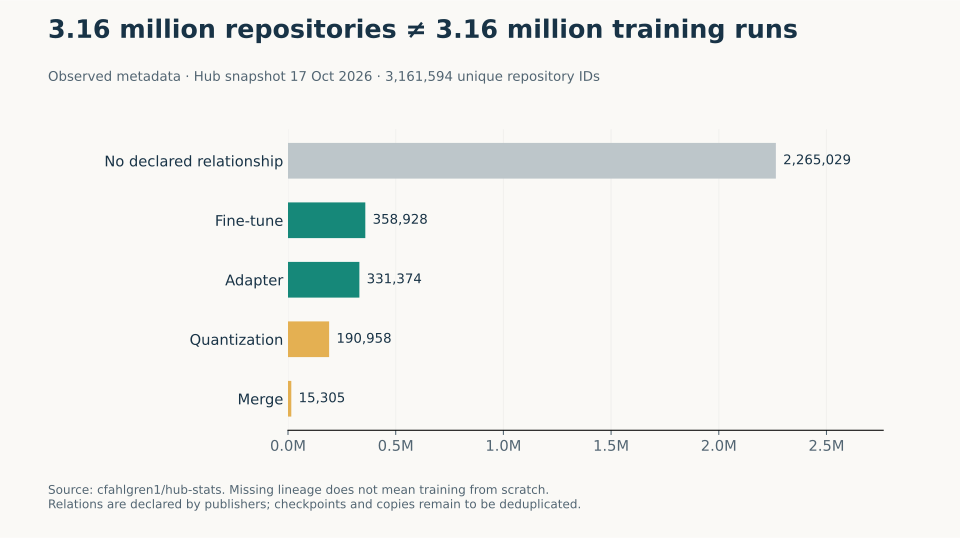
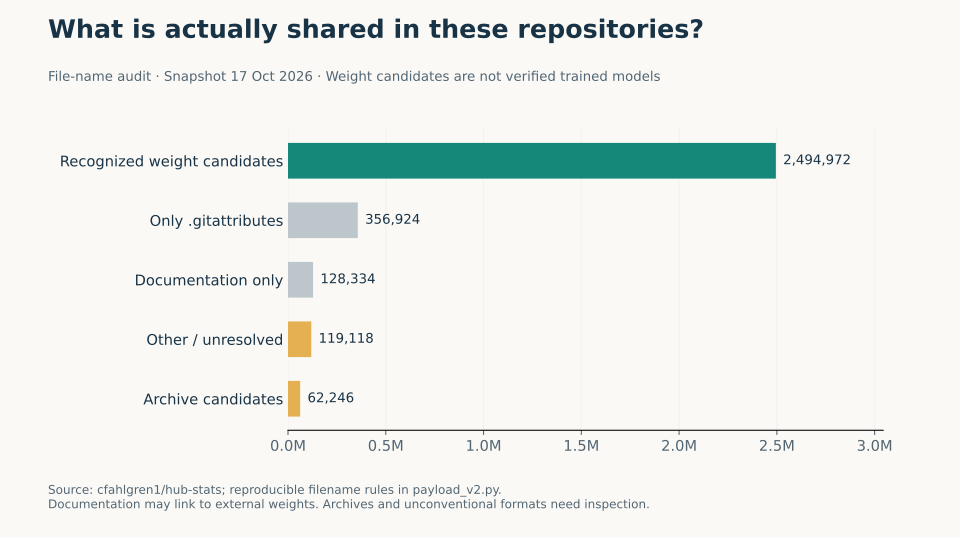
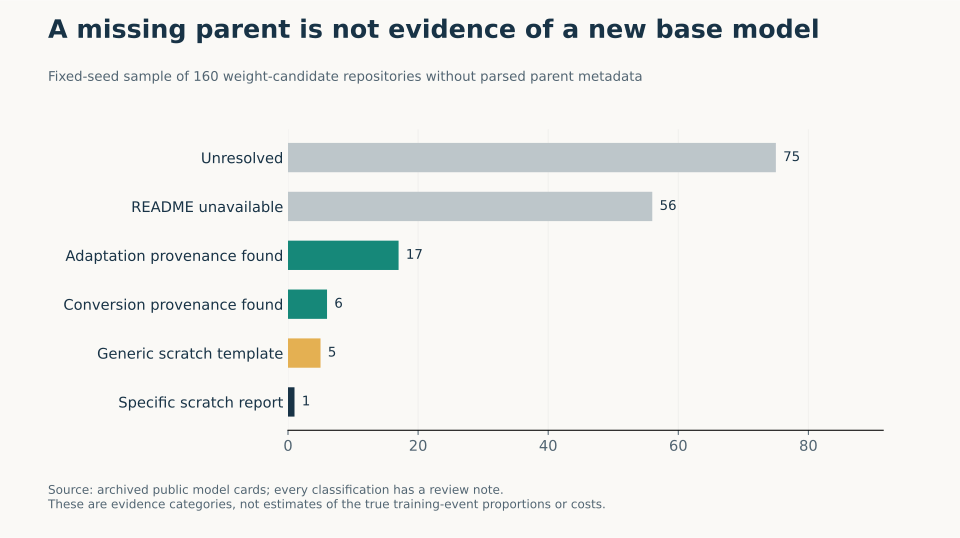
Un échantillon reproductible de 160 dépôts avec poids candidats et sans parent structuré trouve 17 adaptations et 6 conversions avec provenance explicite. Un seul entraînement depuis zéro a un budget exploitable. Les cas non résolus empêchent d’estimer un coût moyen fiable : aucun forfait n’est ajouté au total.
Revue ligne par ligne · Registre des 1 378 modèles ouverts Epoch
| Organisation / famille | Scénario central | Part à volumes renseignés | Bas–haut | Preuves et hypothèses |
|---|---|---|---|---|
| Meta Llama 3 / 3.1 / 3.2 / 3.3 | 111 M$ | 106 M$ | 63–250 M$ | Voir sources et limites3.1 39.3M H100-h + 3.2 text0.916M + vision2.02M =42.236M. Llama3.0 extra7.7M appears ONLY in high pending overlap resolution; 3.3 repeated7.0M not added. Replace generic margin by reported3.2 hours; unresolved3.0 overlap not added centrally. Whether 3.1 8B/70B were continued from 3.0 checkpoints (if yes, 3.0 hours are still real spend for separately released weights but drop for the "count base once" rule). 3.2 card text 916k vs table total 833k+86k. https://github.com/meta-llama/llama-models/blob/main/models/llama3_1/MODEL_CARD.md https://github.com/meta-llama/llama-models/blob/main/models/llama3_2/MODEL_CARD.md https://github.com/meta-llama/llama-models/blob/main/models/llama3_2/MODEL_CARD_VISION.md https://github.com/meta-llama/llama-models/blob/main/models/llama3/MODEL_CARD.md https://github.com/meta-llama/llama-models/blob/main/models/llama3_3/MODEL_CARD.md |
| NVIDIA Nemotron 4 / H | 53 M$ | 46 M$ | 21–155 M$ | Voir sources et limitesC=1e24×[25.80]: 340B×9T (8T+1T continued, card) + H-56B×20T + H-8B×15T (paper §2.4). H-47B (63B-token distillation) excluded. Accepted documented quantity corrections; unreported components stay explicitly assumed. No GPU-hours published for either. FP8 throughput on H100 means FLOP→$ conversion may overstate cost slightly. |
| Moonshot Kimi K3 | 42 M$ | 0 M$ | 7–300 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [9.36, 18.72, 37.44]. 104B actifs. Tokens non publiés; hypothèse 15/30/60T, centrale cohérente avec inférence Epoch, non confirmation. Source notes accepted. Priors held stable: architecture alone does not establish weight ancestry; no new evidence for changed token priors. Pretraining tokens; multimodal (from-scratch MoonViT-V2) token share; RL compute for 9 expert models + multi-teacher consolidation. https://huggingface.co/moonshotai/Kimi-K3 https://github.com/MoonshotAI/Kimi-K3/blob/main/k3_tech_report.pdf |
| Alibaba Qwen 3 | 42 M$ | 31 M$ | 14–130 M$ | Voir sources et limitesC=1e24×[17.2, 20.27, 20.27]: 85.3B active-sum × 30/36/36T (report) + Qwen3-Coder-480B-A35B 1.575 + Qwen3-Next-80B-A3B 0.27 (Epoch 6ND, 7.5T/15T). Coder7.5T independently confirmed in official Qwen blog; Next15T in official card (not only Epoch). Accepted documented quantity corrections; unreported components stay explicitly assumed. Qwen3-Coder 7.5T and Qwen3-Next 15T taken from Epoch (secondary); Qwen3-2507 re-post-training and VL/Omni increments unmeasured. https://huggingface.co/Qwen/Qwen3-235B-A22B https://arxiv.org/html/2505.09388v1 https://huggingface.co/Qwen/Qwen3-Coder-480B-A35B-Instruct |
| Alibaba Qwen 3.8 | 38 M$ | 0 M$ | 7–274 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [8.55, 17.1, 34.2]. 95B actifs; tokens NON publiés : 15/30/60T. Hypothèse nouvel entraînement; filiation avec 3.5 à confirmer. Flash-Next is an unpriced candidate; architecture differences alone do not prove from-scratch initialization. Source notes accepted. Priors held stable: architecture alone does not establish weight ancestry; no new evidence for changed token priors. Tokens for both bases. Whether Flash-Next was distilled/initialised from the 2.4T model. https://huggingface.co/Qwen/Qwen3.8-2.4T-A95B |
| Thinking Machines Inkling / Small | 32 M$ | 20 M$ | 10–123 M$ | Voir sources et limitesC=1e24×[12.15, 14.31, 15.39]: Inkling 41B×45T (PRIMARY, fixed) + Small 12B×15/45/60T (prior). Accepted documented quantity corrections; unreported components stay explicitly assumed. Small tokens; whether 45T counts multimodal tokens the same way (video tokens are cheap per token in some encoders); RL compute. https://huggingface.co/thinkingmachines/Inkling https://huggingface.co/thinkingmachines/Inkling-Small |
| Alibaba Qwen 2.5 | 30 M$ | 0 M$ | 8–90 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [9.396, 14.094, 14.094]. Somme tailles 0.5+1.5+3+7+14+32+72=130.5B; jusqu’à 18T tokens. 12T borne basse car corpus ne garantit pas consommation égale par taille. Coder et VL : marge 0/20/60%, non mesurée. Source notes accepted. Priors held stable: architecture alone does not establish weight ancestry; no new evidence for changed token priors. Per-size token counts not published; Coder (+5.5T continued) and VL in margin. |
| Meituan LongCat Flash + 2.0 | 30 M$ | 24 M$ | 10–204 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [12.5, 13.806, 17]. Flash ~27B actifs×23T (23T estimé Epoch); 2.0 48B×>35T. Mention « millions accelerator-days » sans prix ASIC : borne haute élargie. Source notes accepted. Priors held stable: architecture alone does not establish weight ancestry; no new evidence for changed token priors. ASIC type and rental-equivalent price; exact token count beyond ">35T". |
| Alibaba Qwen 3.5 | 28 M$ | 0 M$ | 5–178 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [6.551999999999999, 13.103999999999997, 26.207999999999995]. Tailles actives 17+10+3+27+9+4+2+0.8B. Tokens NON publiés : hypothèse 15/30/60T par taille; indépendance entre tailles supposée. V1 token prior15/30/60T deliberately unchanged; moving it to20/36/60T is judgement, not new data. Source notes accepted. Priors held stable: architecture alone does not establish weight ancestry; no new evidence for changed token priors. Token counts per size; whether small dense sizes were pruned/distilled from larger ones. |
| DeepSeek DeepSeek V4 Pro + Flash | 26 M$ | 22 M$ | 10–83 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [12.198, 12.198, 12.198]. Pro 49B actifs×33T + Flash 13B×32T. 6ND approximatif pour architecture hybride. Source notes accepted. Priors held stable: architecture alone does not establish weight ancestry; no new evidence for changed token priors. Sparse-attention/hybrid architecture effect on 6ND; Ascend vs NVIDIA share of training hardware. |
| Mistral AI Mistral Medium 3.5 | 25 M$ | 0 M$ | 3–157 M$ | Voir sources et limitesCumulative shared-backbone scenario, not three independent bases:128B-equivalent ×5/15/30T assumed. Shared ancestry with Devstral2/Large2411 supported by sampled weights; no amount of training inferred from correlation. Original numerical prior retained pending real budget disclosure. Source notes accepted. Priors held stable: architecture alone does not establish weight ancestry; no new evidence for changed token priors. Sampled weights show r0.994–0.999 with Devstral2; strong similarity but direction/common trained checkpoint versus common initialization not proven. Tokens and incremental budget remain unknown. https://huggingface.co/mistralai/Mistral-Medium-3.5-128B https://huggingface.co/mistralai/Devstral-2-123B-Instruct-2512 https://mistral.ai/news/vibe-remote-agents-mistral-medium-3-5 https://x.com/mertunsal2020/status/2049551864556143094 https://huggingface.co/mistralai/Devstral-2-123B-Instruct-2512 https://huggingface.co/mistralai/Mistral-Large-Instruct-2411 |
| Tencent Hunyuan Large / Hy3 / Hy4 | 23 M$ | 6 M$ | 5–169 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [6.43, 10.84, 21.130000000000003]. Hunyuan Large C≈3.49e24 selon Epoch; Hy4 49B actifs. Tokens Hy4 supposés 10/25/60T, Hy3 non ajouté comme nouvelle base faute de filiation; risque de double compte Large/Hy4 restant. CORRECTION TO SCOPE: this monetary scenario covers Large + Hy4 only; Hy3 has no separate priced run and is listed as an unpriced candidate. Reported9.59ND FLOPs retained over generic6ND. Source notes accepted. Priors held stable: architecture alone does not establish weight ancestry; no new evidence for changed token priors. Hy3/Hy4 tokens; whether Hy4 initialised from Hy3 (impossible weight-wise without growth, but not documented). https://huggingface.co/tencent/Hy4-preview https://epoch.ai/data/ai-models https://arxiv.org/html/2411.02265 |
| Xiaomi MiMo 7B / V2 Flash / V2.5 Pro | 22 M$ | 19 M$ | 8–70 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [10.284, 10.284, 10.284]. 7B25T; Flash15B27T; Pro42B27T. Autres versions dans marge, pas duplication VL7B. Source notes accepted. Priors held stable: architecture alone does not establish weight ancestry; no new evidence for changed token priors. Whether V2.5-Pro reused V2-Pro (closed) pretraining — if V2-Pro and V2.5-Pro share one 27T run, fine; if V2.5-Pro added more tokens, undercount. https://huggingface.co/XiaomiMiMo/MiMo-V2-Flash |
| NVIDIA Nemotron 3 / 3.5 | 21 M$ | 16 M$ | 8–76 M$ | Voir sources et limitesC=1e24×[9.44]: Ultra 55B×20T + Super 12B×25T + Nano 3.2B×25T + 3.5 Lightning 3B×20T + 3.5 Super-VL increment (1T distillation from Ultra + ~0.3T CPT; student+teacher-forward ≈0.20). Accepted documented quantity corrections; unreported components stay explicitly assumed. NVFP4 pretraining: FLOP→$ at BF16/FP8-calibrated prices may overstate cost by up to ~2× for Ultra/Super/Lightning (Blackwell FP4 throughput); low scenario does not fully capture this. https://huggingface.co/nvidia/NVIDIA-Nemotron-3-Ultra-550B-A55B-Base-BF16 https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-Base-BF16 https://huggingface.co/nvidia/NVIDIA-Nemotron-3-Super-120B-A12B-BF16 https://huggingface.co/nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B-Base-BF16 https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16 |
| Meta Llama 4 Scout + Maverick | 20 M$ | 18 M$ | 11–38 M$ | Voir sources et limites7.38 millions heures H100; $/h = (1.5, 2.5, 4). Scout 5M h; Maverick 2.38M h. Behemoth non publié exclu. Source notes accepted. Priors held stable: architecture alone does not establish weight ancestry; no new evidence for changed token priors. Post-training/RL hours; co-distillation teacher cost. https://github.com/meta-llama/llama-models/blob/main/models/llama4/MODEL_CARD.md |
| Ant Group Ling 1T / 2.6 | 18 M$ | 16 M$ | 7–53 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [8.88, 8.88, 8.88]. Base 50B actifs×20T; Ling2.6 ajoute 9.6T après migration. Ne pas compter deux bases 20T. Retained V1 scenario; not a newly observed budget. |
| China Telecom TeleChat 1 / 2 | 16 M$ | 12 M$ | 6–60 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [7.0284, 8, 10]. 115B10T explicite=6.9e24; Telechat1 7B+12B=.1284e24. PetitsTelechat2 non chiffrés : enveloppe centrale8e24, haute10e24. Retained V1 scenario; not a newly observed budget. |
| Swiss AI Apertus 8B / 70B | 15 M$ | 11 M$ | 6–45 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [7.46, 7.46, 7.46]. 70B6.74e24 FLOP rapportés selon Epoch;8B15T=.72e24. Équivalent GPU pour GH200. Retained V1 scenario; not a newly observed budget. https://huggingface.co/swiss-ai/Apertus-70B-2509 https://github.com/swiss-ai/apertus-tech-report/blob/main/Apertus_Tech_Report.pdf |
| Z.ai GLM 5 / 5.x | 15 M$ | 12 M$ | 5–55 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [6.84, 6.84, 6.84]. 40B actifs×28.5T; prix FLOP équivalent GPU malgré matériel Ascend. Suites et RL ajout 0/25/100%. Retained V1 scenario; not a newly observed budget. |
| TII Falcon 7B / 40B / 180B | 14 M$ | 12 M$ | 6–37 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [4.0614, 4.0614, 4.0614]. 180B 43,500 PF-days publiés; 40B1T et7B1.5T. Prix plus élevé pour génération A100. Retained V1 scenario; not a newly observed budget. |
| Z.ai GLM 4.5 / Air | 13 M$ | 11 M$ | 5–41 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [6.098400000000001, 6.098400000000001, 6.098400000000001]. 32B+12B actifs; 23.1T; variantes officialisées dans marge. Retained V1 scenario; not a newly observed budget. |
| Moonshot Kimi K2 / K2.5 | 13 M$ | 11 M$ | 5–40 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [5.856, 5.856, 5.856]. 32B actifs; K2 15.5T + K2.5 15T supplémentaires. Base K2 comptée une fois. Retained V1 scenario; not a newly observed budget. |
| Upstage Solar Open 100B / Open2 250B | 13 M$ | 13 M$ | 7–22 M$ | Voir sources et limitesOpen2 fiche officielle2M heures B200 ×3/5/8$/h. Open100B12B×19.7T=1.4184e24. Pas ajout des coûts32M/8.4M cités par Epoch (périmètre divergent). Retained V1 scenario; not a newly observed budget. https://huggingface.co/upstage/Solar-Open2-250B |
| MiniMax MiniMax M2 / M3 | 11 M$ | 0 M$ | 2–79 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [1.98, 4.95, 9.9]. 10B/23B actifs. Tokens 10/25/50T et bases distinctes supposés. Rapport M3 lié décrit expérience109B/3T : ce chiffre n’est PAS retenu pour M3. Retained V1 scenario; not a newly observed budget. |
| LG AI Research K-EXAONE 1 / 2 | 11 M$ | 0 M$ | 3–34 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [3.55, 5.07, 5.07]. Estimates Epoch : K2 3.55e24, K1 1.52e24. Faute de filiation démontrée, bas suppose coût K1 inclus, central/haut indépendant; EXAONE antérieurs dans résiduel. Retained V1 scenario; not a newly observed budget. |
| MiniMax MiniMax Text-01 / M1 | 11 M$ | 10 M$ | 5–30 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [5.20506, 5.20506, 5.20506]. Text01 7.2+3.2+1=11.4T; M1 continuation 7.5T. RL publié ~$0.53M ajouté ci-dessous; pas double base. + 0.53 M$ RL dans chaque scénario. Retained V1 scenario; not a newly observed budget. https://huggingface.co/MiniMaxAI/MiniMax-Text-01 |
| Cohere Command R / R+ | 11 M$ | 0 M$ | 1–85 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [1.668, 5.004, 12.51]. 35B et104B; tokens inconnus, hypothèse2/6/15T. Suites inconnues dans marge. Retained V1 scenario; not a newly observed budget. |
| DeepSeek DeepSeek V4.1 Flash | 10 M$ | 0 M$ | 2–69 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [2.16, 4.32, 8.64]. 45T depuis zéro; 8B actifs prefill / 16B decode. Coût effectif entraînement non donné : 8/16/32B équivalents, pas une mesure. Retained V1 scenario; not a newly observed budget. |
| Google Gemma 4 | 9 M$ | 0 M$ | 2–58 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [2.256, 4.23, 8.46]. Tailles31B,26B-A4B,12B; tokens NON publiés. Scénario8/15/30T par taille. TPU convertis en équivalent coût FLOP; ni nombre de TPU ni durée déduite abusivement. Retained V1 scenario; not a newly observed budget. |
| StepFun Step 5 | 9 M$ | 0 M$ | 1–65 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [1.62, 4.05, 8.1]. 27B actifs; tokens non connus 10/25/50T. Step3 et autres familles en résiduel. Retained V1 scenario; not a newly observed budget. |
| StepFun Step Video | 8 M$ | 0 M$ | 1–48 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [1.5, 4.1015808, 8]. Rapport : milliers H800 pendant >1 mois, utilisation32%. Epoch suppose5000 GPU×720h; nombre et durée centraux inférés, non publiés. Texte encodeur non valorisé séparément. Retained V1 scenario; not a newly observed budget. |
| DeepSeek DeepSeek V3 / R1 / V3.x | 8 M$ | 6 M$ | 3–25 M$ | Voir sources et limites2.788 millions heures H800; $/h = (1, 2, 3). V3 publié = 5.576 M$ à 2$/h, dont 2.664M h prétraining. R1 et suites NON couverts par ce chiffre : ajout hypothétique 0/50/200%. Retained V1 scenario; not a newly observed budget. |
| Black Forest Labs FLUX 1 / 2 | 8 M$ | 0 M$ | 1–40 M$ | Voir sources et limitesBudget inconnu. Scénario famille 0.5/3.2/10 millions heures H100 équivalentes ×2/2.5/4$/h. Ni heures ni dollars publiés. Ne comprend pas toutes les générations fermées des teachers. Retained V1 scenario; not a newly observed budget. |
| Baidu ERNIE 4.5 text / VL | 8 M$ | 0 M$ | 2–41 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [2.82, 3.5, 6]. 47B actifs; 10T hypothèse Epoch pour texte=2.82e24. VL partage étapes texte : enveloppe plutôt que seconde base entière. Retained V1 scenario; not a newly observed budget. |
| Meta Llama 2 | 7 M$ | 7 M$ | 3–13 M$ | Voir sources et limites3.3 millions heures A100; $/h = (1, 2, 3). Famille publiée; supplément de post-training supposé. Retained V1 scenario; not a newly observed budget. |
| Google Gemma 3 | 7 M$ | 6 M$ | 3–21 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [3.24, 3.24, 3.24]. 27B14T +12B12T +4B4T +1B2T. Distillation et suites dans marge. Gemma3n non estimé séparément. Retained V1 scenario; not a newly observed budget. |
| Mistral AI Mixtral 8x7B / 8x22B | 6 M$ | 0 M$ | 1–37 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [0.9341999999999999, 3.114, 6.228]. 12.9/39B actifs; tokens 3/10/20T supposés. Central10T reprend hypothèse Epoch, non chiffre publié. Retained V1 scenario; not a newly observed budget. |
| xAI Grok 1 | 6 M$ | 0 M$ | 1–42 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [1.5, 2.9, 7]. Tokens non publiés; C central et bornes issus raisonnement comparatif Epoch, pas mesure de dépense. Retained V1 scenario; not a newly observed budget. |
| OpenAI gpt-oss 120B / 20B | 6 M$ | 6 M$ | 3–12 M$ | Voir sources et limites2.31 millions heures H100; $/h = (1.5, 2.5, 4). Rapport :120B 2.1M h,20B presque10x moins; approximation0.21M h. Posttraining couverture incertaine : pas supplément central pour éviter de recompter. Retained V1 scenario; not a newly observed budget. |
| Google Gemma 2 | 6 M$ | 5 M$ | 2–16 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [2.562, 2.562, 2.562]. 27B13T +9B8T +2B2T; teacher inference/distillation via supplément 0/20/60%. Retained V1 scenario; not a newly observed budget. |
| Databricks DBRX | 5 M$ | 5 M$ | 2–16 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [2.592, 2.592, 2.592]. 36B actifs×12T; ne transforme pas les3 mois développement en3 mois de cluster. Retained V1 scenario; not a newly observed budget. https://www.databricks.com/blog/introducing-dbrx-new-state-art-open-llm |
| Stability AI Stable Diffusion 1 / 2 / XL / 3 / 3.5 | 5 M$ | 0 M$ | 1–25 M$ | Voir sources et limitesScénario cumulé 0.5/2/6.25 millions heures GPU équivalentes ×2/2.5/4$/h; sparse budgets historiques, surtout inconnus pour3.5. Nouvelles versions comptées avec enveloppe, pas par repo. Retained V1 scenario; not a newly observed budget. https://arxiv.org/html/2403.03206 https://huggingface.co/stabilityai/stable-diffusion-xl-base-1.0 |
| Ai2 OLMo 2 | 4 M$ | 3 M$ | 1–10 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [1.71, 1.71, 1.71]. 7B4T,13B5T,32B6T; annealing et adaptations dans marge. Retained V1 scenario; not a newly observed budget. |
| Alibaba Wan 2.1 / 2.2 | 3 M$ | 0 M$ | 0–15 M$ | Voir sources et limitesScénario 0.25/1.2/3.75 millions heures GPU ×2/2.5/4$/h. Paramètres et corpus publiés insuffisants pour durée; 6ND texte non appliqué aux images. Retained V1 scenario; not a newly observed budget. |
| Arcee / Prime Intellect Trinity Large | 3 M$ | 2 M$ | 1–8 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [1.326, 1.326, 1.326]. 13B actifs×17T finaux; TrueBase10T intermédiaire non ajouté. Retained V1 scenario; not a newly observed budget. |
| BigScience BLOOM | 2 M$ | 0 M$ | 1–4 M$ | Voir sources et limites1.078272 millions heures A100; $/h = (1, 2, 3). Heures run final reprises dans Epoch. Fourchette publique 2–5M$ inclut expériences : pas une facture du run final. Retained V1 scenario; not a newly observed budget. |
| DeepSeek DeepSeek V2 | 2 M$ | 2 M$ | 1–6 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [1.0206, 1.0206, 1.0206]. 21B actifs × 8.1T tokens; Lite et adaptations via marge. Retained V1 scenario; not a newly observed budget. |
| Microsoft Phi 4 | 2 M$ | 1 M$ | 1–6 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [0.8232, 0.8232, 0.8232]. 14B×9.8T; petites variantes et adaptations dans enveloppe. Retained V1 scenario; not a newly observed budget. |
| IBM Granite 3 dense | 1 M$ | 1 M$ | 1–4 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [0.72, 0.72, 0.72]. 8B et2B ×12T; MoE, autres générations Granite en résiduel. Retained V1 scenario; not a newly observed budget. |
| OpenAI Whisper | 1 M$ | 0 M$ | 0–5 M$ | Voir sources et limitesC (10^24 FLOP), bas/central/haut = [0.15, 0.4, 0.8]. Epoch donne v3≈2.7e23 FLOP et v2≈1.1e23; enveloppe versions et incertitude. Pas toutes les adaptations communautaires. Retained V1 scenario; not a newly observed budget. |
Une part renseignée affichée à 0 signifie «aucune composante retenue dans ce sous-total», jamais «entraînement gratuit».
Des comparaisons de tranches de poids révèlent de fortes similarités entre Devstral 2 et Medium 3.5, ainsi qu’entre les Qwen 27B. Elles signalent des risques de double compte, sans mesurer les tokens supplémentaires. Architecture seule et corrélation seule ne suffisent pas à reconstruire un budget.
Prix constants identiques à V1 pour isoler les corrections de données. Le tarif public Lambda actuel H100 est distinct de notre hypothèse de location en volume. Les contrats, l’amortissement et les millésimes restent inconnus.
Hypothèses de prix et références publiques · Résumé JSON · Schéma et règles d’utilisation